Connected tools and condition monitoring
A vibration sensor can report a change in a machine. Whether that information prevents a breakdown depends on what the maintenance team does next, how much warning it has, and whether the reported change actually indicates a developing fault. Connectivity makes information available. It does not complete the maintenance decision.
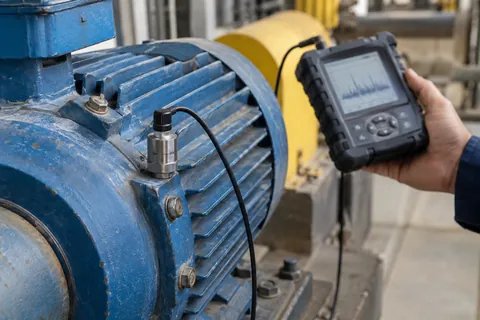
As of October 10, 2025. Two strands of 2025 research sharpen that distinction. A review involving NIST examines how monitoring technologies are evaluated economically and operationally. A September preprint examines why bearing-diagnosis algorithms can appear more capable in a benchmark than they are on unfamiliar components. Together, they offer a useful way to assess the claims attached to connected equipment.
Start with the failure that matters
Monitoring is easier to justify when the team can identify a failure mode and an intervention that changes its consequences. A slowly developing bearing problem, for example, may provide a useful opportunity to schedule inspection or replacement. A sudden failure with no reliable measurable precursor presents a different challenge.
The asset's role also matters. A fault in a production bottleneck may interrupt an entire line. A similar fault in equipment with readily available redundancy may have a smaller operational consequence. The same sensor package can therefore have different value on apparently similar machines.
ISO 17359:2018 provides an established general framework for setting up a machine condition-monitoring programme. Its publicly available scope concerns the procedures to consider, rather than approval of a particular sensor or algorithm. That programme-level perspective remains relevant as wireless devices and cloud services become easier to buy.
Before specifying connectivity, define the decision. Who reviews an alert? What evidence prompts a work order? How quickly can someone inspect the machine? Are parts and an appropriate shutdown window available? If these questions remain unanswered, a better signal may simply produce an earlier warning that nobody can use.
The evidence base measures different things
The 2025 review by Dadfarnia, Sharp and Herrmann examined condition-monitoring evaluation studies with operational and economic relevance. From 465 relevant peer-reviewed studies covering 2001–2023, 42 met its eligibility criteria. The authors found limited manufacturing-specific evidence and substantial variation in methods, performance measures and economic assumptions.
The review does not conclude that monitoring lacks value. It shows why results from different applications cannot be combined casually into one expected saving. Studies that report classification accuracy are answering a different question from studies that examine availability, maintenance decisions and cost.
For an equipment buyer, that distinction can improve a supplier discussion. Ask whether a claimed improvement was observed in operation, calculated in a simulation, or estimated from assumed failures. Establish whether the comparison included the existing preventive maintenance programme. A saving against an unrealistic run-to-failure baseline may not describe the improvement available at a well-maintained plant.
Also check what the cost boundary includes. Sensors, installation and subscriptions are visible expenses. Reviewing alerts, maintaining communications, replacing batteries and investigating false alarms consume resources too. The business case should include the work required to keep the monitoring system useful over its life.
A benchmark can accidentally test familiarity
A preprint released on September 26 investigates data leakage in bearing-fault diagnosis. Its central concern is that portions of recordings from the same physical bearing can appear in both training and testing. An algorithm can then benefit from familiar signal characteristics rather than demonstrate its ability to diagnose an unseen bearing.
The authors evaluated different splitting methods across three public datasets and reported large changes in performance under stricter separation. Their proposed approach keeps data from an individual bearing on one side of the train-test boundary. The work is a preprint and a benchmark investigation, not a field audit of every commercial monitoring product.
Its purchasing implication is nevertheless concrete. A reported score needs a description of the test population. Was the model assessed on different recordings from familiar equipment, entirely new bearings, another machine type, or a different site? These are progressively different questions, and a high score on one does not answer all the others.
An illustrative analogy is learning the sound of one noisy motor and then recognising it in another recording. That can be useful for tracking the same asset, but it does not by itself demonstrate recognition of the same fault in an unfamiliar motor. The intended deployment should determine which test is meaningful.
Public datasets are useful within their boundaries
Case Western Reserve University's Bearing Data Center describes experiments using a motor test arrangement with deliberately introduced bearing faults. The data have clear value for studying diagnostic methods because the experimental conditions and fault locations are documented. They do not represent an unfiltered record of all the ways equipment deteriorates across factories.
Paderborn University's Bearing DataCenter provides vibration and motor-current measurements with documented operating conditions and bearing damage. Its associated 2016 research is another established resource for comparing methods. The university also sets out noncommercial-use conditions, which matter when a company wants to move from academic experimentation to a commercial application.
For a maintenance manager, the lesson is to ask how laboratory evidence is supplemented. The relevant plant may have changing loads, installation differences, background vibration and a different history of lubrication or repair. A method should be checked against the conditions it will encounter, including periods when the equipment is healthy.
A trial that only contains known faults can make detection look straightforward while revealing little about false alerts during ordinary operation. Conversely, a short trial with no failures cannot establish that rare failures will be detected. Both limitations should remain visible when the pilot is reviewed.
Turn alerts into an auditable maintenance record
Consider a hypothetical pump with a rising vibration indicator. The useful record includes operating conditions, the sensor location, the alert, the inspection decision and what the inspection found. If the machine is repaired, the team should record the fault and whether the indicator returned to its expected range.
That feedback helps distinguish a meaningful warning from a change caused by load, installation or measurement. It also exposes an organisational failure when a valid warning was received but no timely action followed. Counting alerts would miss that distinction.
Evaluate lead time in relation to the available intervention. Several days of warning may be valuable when a replacement is stocked and the plant has regular maintenance windows. The same warning may be insufficient for a component with a long supply lead time. An accuracy score alone says nothing about this relationship.
Escalation should reflect uncertainty. Some alerts justify a planned check; others may require a more urgent review under the site's procedures. The monitoring service needs to communicate what it knows and what remains uncertain so that people can make an appropriate decision. A dashboard colour should not obscure the evidence behind it.
Judge the programme over normal operation
A practical pilot should include a defined asset group, a documented baseline and measures that the maintenance team can actually verify. Track confirmed defects, missed defects discovered through other routes, false alerts, response time and the cost of the resulting work. Record changes in production conditions so they are not mistaken for a monitoring effect.
Avoid claiming a prevented breakdown every time a component is replaced after an alert. Inspection may show that the replacement was prudent, but the exact failure date without intervention usually remains unknown. Describe the observed condition and the action taken rather than inventing a counterfactual event.
Expansion becomes easier to justify when the pilot produces dependable decisions with manageable effort. Some assets may benefit from continuous monitoring, while others may be served adequately by periodic measurements or existing inspections. The evidence should determine the allocation.
Connected tools are valuable when they help a maintenance team act on a real problem at a useful time. The strongest programme connects measurement to diagnosis, diagnosis to a decision, and the decision to a recorded outcome. That complete chain is what turns sensor data into better equipment management.